
JavaScript Object Notation (JSON) has long served as the bedrock of modern data exchange, web development, and application configuration. Its human-readable syntax, native support across virtually every programming language, and seamless integration with document-oriented databases have made it an indispensable format for developers worldwide. Within the Python ecosystem, working with JSON is traditionally straightforward. For modest data payloads, developers rely heavily on Python’s built-in json module, which offers simple methods like json.load() and json.loads() to deserialize files into native Python dictionaries, lists, strings, and numeric types.
However, as big data practices expand into everyday software engineering, developers frequently encounter datasets scaling into hundreds of megabytes or even several gigabytes. When applied to files of this magnitude, standard parsing techniques often break down, leading to severe performance degradation, out-of-memory crashes, and server instability. This article examines the architectural bottlenecks of traditional JSON parsing in Python, explores the mechanics of memory bloat, and demonstrates how iterative parsing libraries like ijson provide a scalable, memory-efficient solution for enterprise-grade data processing pipelines.
The Architectural Bottleneck of Traditional JSON Parsing
To understand why large JSON files cripple standard parsing tools, one must examine how the built-in json module operates under the hood. When a developer invokes json.load() on a file stream, Python reads the entire document into memory and constructs an exhaustive abstract syntax tree representing every key, value, array, and nested object. Only after this complete deserialization process finishes does the application gain access to the data structure.
While this approach works seamlessly for files spanning a few kilobytes or megabytes, it introduces a dangerous linear scaling relationship between file size on disk and random-access memory (RAM) consumption. Furthermore, the memory footprint of a parsed JSON document is almost always significantly larger than the physical file size on disk. A compact text representation of a string or integer expands into a richly annotated Python object containing reference counts, type headers, and dictionary hash tables. Consequently, a file occupying 181 megabytes on a storage drive can easily consume upwards of 800 megabytes of active RAM once fully loaded into Python’s runtime environment.
In cloud computing environments, serverless functions, and containerized microservices with strict memory limits, hitting these thresholds triggers immediate Out-Of-Memory (OOM) kills. Developers are frequently forced to provision larger, more expensive server instances simply to parse data structures that they only intend to query or filter sequentially.
Establishing the Experimental Baseline: The San Francisco City Lots Dataset
To evaluate the practical implications of memory bloat and streaming alternatives, software engineers can test workflows against publicly available spatial datasets. A prime candidate for this benchmark is the San Francisco City Lots dataset, hosted widely on public repositories such as GitHub. Originally sourced from municipal geographic information systems, this dataset conforms to the standard GeoJSON specification, organizing municipal land parcels into a hierarchical FeatureCollection.
Downloading the dataset via standard shell commands reveals a compressed size of approximately 181 megabytes. A preliminary inspection using Python’s native json module demonstrates the high-level structure of the document:
import json

with open("citylots.json", "r") as f:
    data = json.load(f)

print(data.keys())
print(data["features"][0])
The resulting schema divides the data into root-level keys, primarily type and features. The features array contains over 200,000 individual elements. Each element represents a specific land parcel, housing two primary child objects: properties (containing alphanumeric metadata such as block numbers, lot numbers, and street names) and geometry (containing complex polygon coordinates used for geographic mapping).
In many analytical workflows, a data scientist or urban planner may only require metadata attributes—such as identifying which parcels reside on a specific thoroughfare—while completely ignoring the heavy geometric coordinate arrays. Yet, when employing standard parsing methods, the interpreter is forced to ingest every single coordinate point into memory before a single line of business logic can execute.
Measuring Memory Consumption and Performance Metrics
When executing a standard parsing script designed to search for parcels situated along Market Street within the San Francisco dataset, the performance metrics highlight the hidden costs of full-document deserialization. Using profiling tools such as memory-profiler, developers can map the exact allocation of RAM line by line.
A standard implementation utilizing json.load() reveals a stark memory spike precisely at the moment of file ingestion:
from memory_profiler import profile
import json

@profile
def process_file():
    with open("citylots.json", "r") as f:
        data = json.load(f)
    features = data["features"]
    market_count = 0
    for feature in features:
        if feature["properties"].get("STREET") == "MARKET":
            market_count += 1

process_file()
When executing this profiler, the output consistently demonstrates that parsing the 181-megabyte file causes an immediate memory increment of over 760 megabytes, bringing total process memory close to 809 megabytes. The script successfully tallies the 808 matching parcels out of 206,560 total entries and completes execution in approximately 4 seconds. However, the resource-to-output ratio is wildly disproportionate: processing a fraction of a megabyte of relevant text required maintaining nearly a gigabyte of redundant geographic coordinates in active memory.
Transitioning to Iterative Streaming with ijson
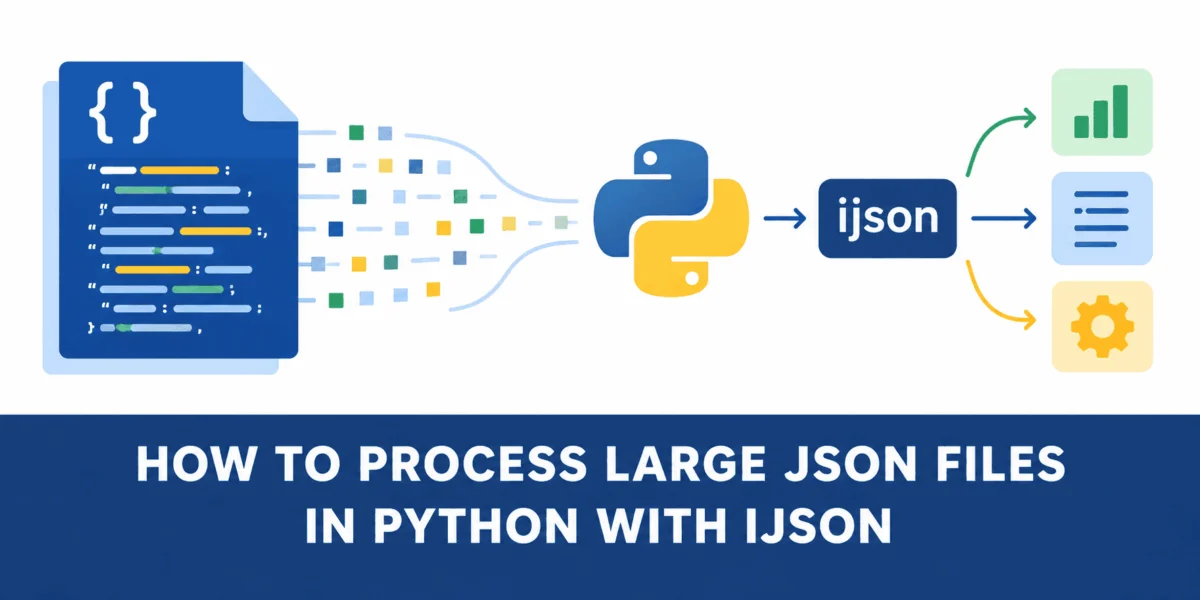
To eliminate this memory overhead, developers must shift from a load-and-parse model to an iterative streaming architecture. Libraries like ijson provide this capability by implementing a pull-parser that reads JSON streams incrementally, parsing tokens on the fly without constructing the entire document tree in memory.
By utilizing ijson.items(), developers can target specific paths within a JSON hierarchy and process matching elements one by one. For the San Francisco dataset, the target path is defined as features.item, instructing the parser to yield each individual feature dictionary residing within the root features array sequentially.
The implementation of an iterative streaming script modifies the file-reading protocol to operate on byte streams and processes records inside a generator loop:
import ijson
import time

start = time.perf_counter()
total = 0
market_count = 0
first_five = []

with open("citylots.json", "rb") as f:
    for feature in ijson.items(f, "features.item"):
        total += 1
        properties = feature["properties"]
        if properties.get("STREET") == "MARKET":
            market_count += 1
            if len(first_five) < 5:
                first_five.append(properties.get("BLKLOT"))

elapsed = time.perf_counter() - start

print(f"Total parcels: total:,")
print(f"Market Street parcels: market_count:,")
print(f"First five parcel IDs: first_five")
print(f"Time: elapsed:.2f seconds")
Under this streaming paradigm, the execution lifecycle transforms fundamentally. Instead of reading the entire file, parsing every object, creating all Python dictionaries, and storing everything in memory simultaneously, the application adopts a read-process-discard workflow. Each feature is loaded into memory, evaluated against the filtering logic, and immediately garbage-collected as the loop advances to the next item.
Comparative Analysis: Memory Footprint and Execution Efficiency
Running identical memory profiling diagnostics on the ijson-based implementation yields a dramatic reduction in resource utilization. While the baseline Python runtime and file buffer consume roughly 43 to 46 megabytes of memory, the incremental memory spike during file processing is virtually nonexistent.
| Approach | Input File Size | Peak Memory Usage | Processing Model | Execution Time |
|---|---|---|---|---|
json.load() |
181 MB | 808.9 MiB | Load entire document tree | ~4.01 seconds |
ijson.items() |
181 MB | 46.1 MiB | Stream records incrementally | ~4.58 seconds |
| Variance | N/A | ~762.8 MiB savings | Shift from batch to stream | Marginal trade-off |
As illustrated in the comparative performance breakdown, streaming the dataset reduces peak memory consumption by more than 760 megabytes—a reduction of over 94 percent. This efficiency comes with a negligible time trade-off; the iterative parser takes approximately half a second longer to execute due to the overhead of incremental tokenization and parsing. In production environments where memory constraints dictate infrastructure costs, trading a fraction of a second of processing time for a massive reduction in RAM requirements is an overwhelmingly favorable optimization.
Broader Implications for Data Engineering and Software Architecture
The architectural lessons demonstrated by comparing json.load() and ijson extend far beyond simple script optimization. As modern enterprises ingest increasingly massive data feeds from APIs, Internet of Things (IoT) sensors, and geospatial databases, data pipelines must be engineered with resource resilience in mind.
Relying on default library methods without evaluating dataset scale represents a common anti-pattern in software development. Code that functions flawlessly during local testing on small sample files frequently fails catastrophically when deployed to production environments processing full-scale enterprise payloads. By adopting streaming parsers for large-scale JSON, XML, or CSV data ingestion, engineering teams can build robust, horizontally scalable pipelines capable of handling arbitrary file sizes without necessitating disproportionate hardware upgrades.
Ultimately, the choice of parsing strategy underscores a fundamental rule of systems architecture: software should consume resources proportional to the units of work being actively processed, rather than scaling boundlessly with the total volume of data at rest.